The discrete AdaBoost loop: weighted error, the learner weight alpha, the multiplicative weight update and the weighted vote. Prove that the newest learner always ends up with error exactly one half, run three rounds by hand on the twelve points, and code the loop in NumPy.
ML02.3.2L2 Intermediate25 minIn review (what this means)
The maths and code on this page are checked by automated tests on every change, but an independent reader has not signed it off yet. Spot a mistake or a confusing step? Tell us.
State the discrete AdaBoost loop with labels in {-1, +1}: weighted error, learner weight, weight update and final vote.
Prove that after the update the learner just added has weighted error exactly one half, and derive the multipliers 1/(2 epsilon) and 1/(2(1 - epsilon)).
Run three rounds of AdaBoost by hand on the twelve points, with every weight as a fraction.
Implement AdaBoost from scratch in NumPy and reconcile it with scikit-learn’s AdaBoostClassifier.
The question
Lesson ML02.3.1 said “make the misses heavier” and “let the stumps vote”. How much heavier, exactly, and how much say should each stump get? AdaBoost answers both with one number per round, and the answer has a surprising property: it always leaves the newest stump looking like a coin flip.
From the last lesson
1. Define the weighted error of a classifier.
Show answer
The total weight of the training points it gets wrong, with weights that sum to 1.
2. With equal weights, what is the best stump on the twelve points and its error?
Show answer
\({x_1 \le 3.5}\), with \({-1}\) on the left and \({+1}\) on the right. It misses \((2,5)\) and \((5,5)\), so its error is \({2/12 = 1/6}\).
Intuition
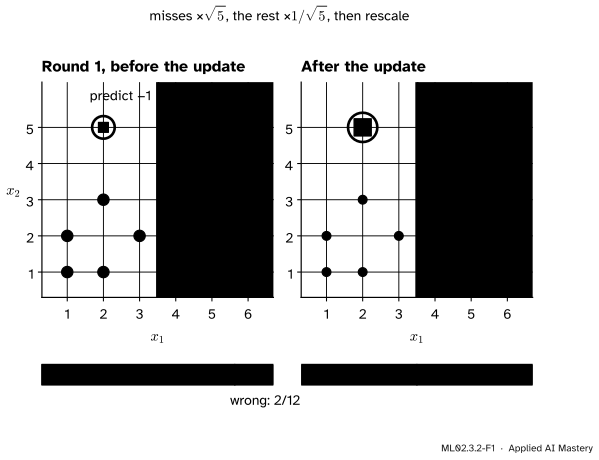
AdaBoost reweights by a rule with a clean aim: after the update, the points the newest stump got wrong must hold exactly half of all the weight. The newest stump then scores no better than a coin on the new weights, so the next round cannot simply pick it again; it must find a rule that does well on its mistakes.
ML02.3.2-F1
Before the update the stump’s mistakes hold \(2/12\) of the weight. Multiplying the misses by \(\sqrt5\) and the rest by \(1/\sqrt5\), then rescaling to a total of 1, leaves the mistakes with exactly one half.
The same factor \(\sqrt5\) decides the stump’s say in the final vote: its learner weight is \({\alpha_1 = \ln\sqrt5 = \tfrac12 \ln 5}\). A more accurate stump gets a larger factor, so its mistakes are made heavier and its vote counts for more.
Build it up
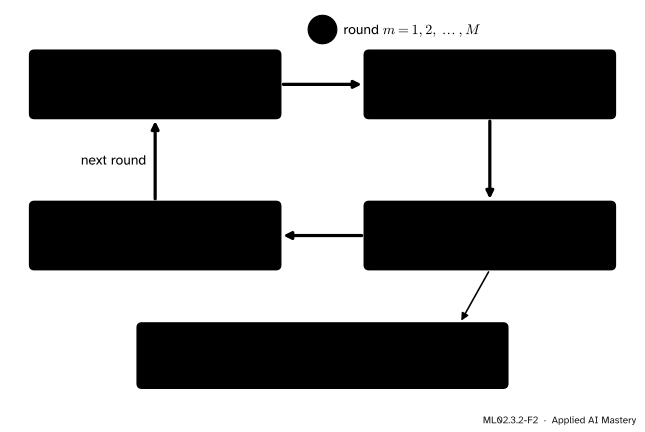
Step 1. Start level. Every point gets weight \({w_i = 1/n}\).
Step 2. Fit the best weak learner. Find the stump \(h_m\) with the smallest weighted error \(\epsilon_m\), as in ML02.3.1.
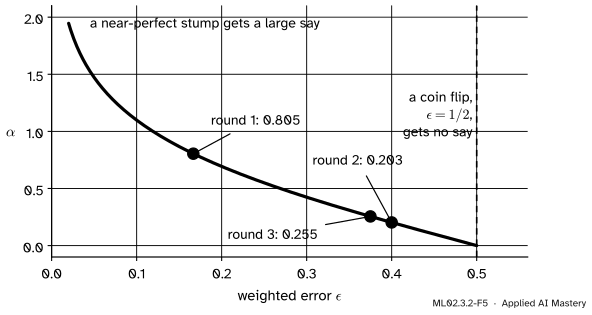
A stump with \({\epsilon_m = \tfrac12}\) gets \({\alpha_m = 0}\); one with \(\epsilon_m\) near 0 gets a very large say.
Step 4. Reweight. Multiply each weight by \({e^{-\alpha_m y_i h_m(x_i)}}\). A point the stump gets right has \({{y_i h_m(x_i)} = 1}\) and shrinks by \({e^{-\alpha_m}}\); a miss has \({{y_i h_m(x_i)} = -1}\) and grows by \(e^{\alpha_m}\). Then divide by the new total \(Z_m\) so the weights sum to 1 again.
Step 5. Repeat, then vote. After \(M\) rounds the combined score is \({F_M(x) = \sum_m \alpha_m h_m(x)}\) and the prediction is its sign.
ML02.3.2-F2
One round of AdaBoost. The loop runs \(M\) times; the stumps and their \(\alpha_m\) are kept for the final weighted vote.
The formal statement
NoteAlgorithm: discrete AdaBoost
Given \((x_1, y_1), \dots, (x_n, y_n)\) with \({y_i \in \{-1, +1\}}\), set \({w_i = 1/n}\). For \({m = 1, \dots, M}\):
Fit \(h_m\) to the weighted data and compute \({\epsilon_m = \sum_i w_i\, I[h_m(x_i) \neq y_i]}\).
Set \({\alpha_m = \tfrac12 \ln\big((1 - \epsilon_m)/\epsilon_m\big)}\).
Set \({w_i \leftarrow w_i\, e^{-\alpha_m y_i h_m(x_i)} / Z_m}\), with \(Z_m\) the sum of the new weights before dividing.
Output the classifier \(\operatorname{sign} F_M(x)\), where \({F_M(x) = \sum_{m=1}^{M} \alpha_m h_m(x)}\).
ML02.3.2-F5
The learner weight falls as the error rises and reaches 0 at a coin flip. The three stumps of the worked example sit on the curve.
The newest learner ends at one half. Write \({\epsilon = \epsilon_m}\) and \({\alpha = \alpha_m}\), and let the weights before the update sum to 1. The misses hold \(\epsilon\) and grow by \(e^{\alpha}\); the rest hold \({1 - \epsilon}\) and shrink by \({e^{-\alpha}}\). From the definition of \(\alpha\),
The two halves are equal. Their sum is the normaliser,
\[
Z_m = 2\sqrt{\epsilon(1-\epsilon)} ,
\]
and after dividing, each side holds exactly \(\tfrac12\). So the weighted error of \(h_m\) under the new weights is \(\tfrac12\): the next round, looking for error below \(\tfrac12\), must choose a different rule.
The same update, as two plain multipliers. Dividing the factors by \(Z_m\),
For a miss, \({\sqrt{(1-\epsilon)/\epsilon}}\) divided by \({2\sqrt{\epsilon(1-\epsilon)}}\) leaves \(1/(2\epsilon)\); for a hit the same steps leave \({1/(2(1-\epsilon))}\). These make hand calculation easy.
Go deeper: other books write alpha without the one half
The algorithm AdaBoost.M1 of The Elements of Statistical Learning (Algorithm 10.1) sets \({\alpha_m = \ln\big((1-\epsilon_m)/\epsilon_m\big)}\), twice ours, and multiplies only the misses by \(e^{\alpha_m}\). Both changes are harmless. Doubling every \(\alpha_m\) doubles \(F_M\) and leaves its sign alone. And multiplying the misses by \(e^{2\alpha}\) while leaving the rest alone is our update multiplied through by \(e^{\alpha}\), a common factor that the rescaling removes. scikit-learn follows the same convention, so its estimator_weights_ are twice our \(\alpha_m\).
Worked example
Three rounds on the twelve points. Labels are \({-1}\) for \((1,1)\), \((2,1)\), \((1,2)\), \((2,3)\), \((3,2)\), \((5,5)\) and \({+1}\) for \((4,1)\), \((5,2)\), \((5,3)\), \((4,4)\), \((2,5)\), \((6,5)\). Stumps are searched as in ML02.3.1, and an exact tie keeps the first stump found.
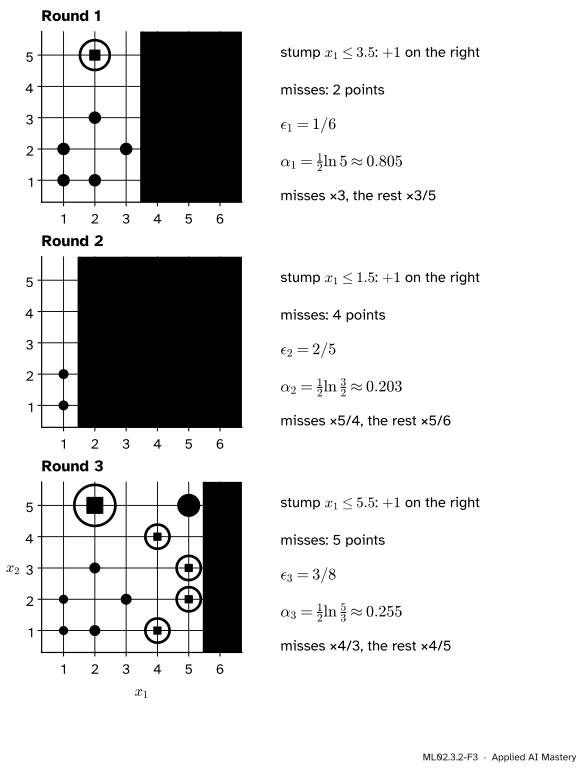
Round 1. Every weight is \(1/12\). The best stump is \({x_1 \le 3.5}\) with \({+1}\) on the right; it misses \((5,5)\) and \((2,5)\), so
The misses are multiplied by \({1/(2\epsilon_1) = 3}\) and become \({3/12 = 1/4}\) each; the rest by \({1/(2 \cdot \tfrac56) = 3/5}\) and become \(1/20\) each.
Round 2. Under these weights four stumps tie at error \(2/5\): \({x_1 \le 1.5}\) with \({+1}\) on the right, \({x_1 \le 4.5}\) with \({+1}\) on the left, and \({x_2 \le 2.5}\) and \({x_2 \le 3.5}\) with \({+1}\) above. The first found is \({x_1 \le 1.5}\). It misses \((2,1)\), \((2,3)\), \((3,2)\) at \(1/20\) each and \((5,5)\) at \(1/4\):
The misses are multiplied by \(5/4\): \((2,1)\), \((2,3)\), \((3,2)\) become \(1/16\) and \((5,5)\) becomes \(5/16\). The rest are multiplied by \(5/6\): the seven \(1/20\) points become \(1/24\) and \((2,5)\) becomes \(5/24\).
Round 3. The best stump is \({x_1 \le 5.5}\) with \({+1}\) on the right, which predicts \({-1}\) everywhere except at \((6,5)\). It misses \((4,1)\), \((5,2)\), \((5,3)\), \((4,4)\) at \(1/24\) each and \((2,5)\) at \(5/24\):
The trace of three rounds. Each round’s stump is fitted to the weights its predecessors set, and its misses are rescaled to hold half of the weight.
The vote after three rounds. All three stumps split \(x_1\), so \(F_3\) is a staircase in \(x_1\): \({-1.263}\) for \({x_1 \le 1.5}\), \({-0.857}\) up to \(3.5\), \({+0.752}\) up to \(5.5\) and \({+1.263}\) beyond. Its sign changes only at \({x_1 = 3.5}\), so the vote still makes the two mistakes of round 1. What changed is the confidence: \((1,1)\) and \((6,5)\) now sit further from the boundary than before. Lesson ML02.3.3 shows why stumps cannot fix those last two points here.
Code
The loop from scratch, reusing the stump search of ML02.3.1.
import numpy as npX = np.array([(1, 1), (2, 1), (1, 2), (2, 3), (3, 2), (5, 5), (4, 1), (5, 2), (5, 3), (4, 4), (2, 5), (6, 5)], dtype=float)y = np.array([-1] *6+ [1] *6)def stump_predict(X, j, t, s):return np.where(X[:, j] > t, s, -s)def fit_stump(X, y, w): best, best_err =None, np.inffor j inrange(X.shape[1]): values = np.unique(X[:, j])for t in (values[:-1] + values[1:]) /2:for s in (1, -1): err = w[stump_predict(X, j, t, s) != y].sum() / w.sum()if err < best_err -1e-12: best, best_err = (j, float(t), s), errreturn best, best_errdef adaboost(X, y, rounds, fit=None):"""Discrete AdaBoost. `fit(X, y, w)` returns a predict function; by default the best stump.""" w = np.full(len(y), 1/len(y)) learners, alphas, history = [], [], []for m inrange(rounds):if fit isNone: (j, t, s), _ = fit_stump(X, y, w) h =lambda Z, j=j, t=t, s=s: stump_predict(Z, j, t, s)else: h = fit(X, y, w) pred = h(X) eps = w[pred != y].sum() / w.sum() alpha =0.5* np.log((1- eps) / eps) w = w * np.exp(-alpha * y * pred) w = w / w.sum() learners.append(h); alphas.append(alpha); history.append((eps, w.copy()))return learners, np.array(alphas), historylearners, alphas, history = adaboost(X, y, 3)for m, (eps, w) inenumerate(history, 1):print(f"round {m}: eps = {eps:.4f}, alpha = {alphas[m -1]:.4f}, "f"weight now on its misses = {w[learners[m -1](X) != y].sum():.4f}")F =sum(a * h(X) for a, h inzip(alphas, learners))print("F_3 on the twelve points:", np.round(F, 3))print("training error:", np.mean(np.sign(F) != y))
round 1: eps = 0.1667, alpha = 0.8047, weight now on its misses = 0.5000
round 2: eps = 0.4000, alpha = 0.2027, weight now on its misses = 0.5000
round 3: eps = 0.3750, alpha = 0.2554, weight now on its misses = 0.5000
F_3 on the twelve points: [-1.263 -0.857 -1.263 -0.857 -0.857  0.752  0.752  0.752  0.752  0.752
 -0.857  1.263]
training error: 0.16666666666666666
Now scikit-learn. Its estimator_weights_ should be twice our \(\alpha_m\), as the .deeper note explained. They are for two rounds; in round 3 the library’s stump, which splits by weighted Gini, picks \({x_1 \le 1.5}\) again, and both its leaves predict \({-1}\), so its error is \(5/12\) rather than \(3/8\).
from sklearn.ensemble import AdaBoostClassifierfrom sklearn.tree import DecisionTreeClassifierclf = AdaBoostClassifier(DecisionTreeClassifier(max_depth=1), n_estimators=3, random_state=0).fit(X, y)print("library weights / 2:", np.round(clf.estimator_weights_ /2, 4))print("library errors: ", np.round(clf.estimator_errors_, 4))# Plug the library's own stump into our loop: 50 rounds now agree exactly.fit_lib =lambda X, y, w: DecisionTreeClassifier(max_depth=1, random_state=0).fit(X, y, sample_weight=w).predict_, ours, _ = adaboost(X, y, 50, fit=fit_lib)lib = AdaBoostClassifier(DecisionTreeClassifier(max_depth=1), n_estimators=50, random_state=0).fit(X, y)print("largest gap over 50 rounds:", np.abs(2* ours - lib.estimator_weights_).max())
library weights / 2: [0.8047 0.2027 0.1682]
library errors:      [0.1667 0.4    0.4167]
largest gap over 50 rounds: 1.2212453270876722e-15
With the same weak learner the two loops agree to rounding error; the only difference was the stump’s splitting score.
Explore
ML02.3-X1
AdaBoost stepper
Press Step to add one learner at a time and watch its misses grow, its \(\epsilon_m\) and \(\alpha_m\) join the table, and the shaded vote redraw. With stumps the training error stays at \(2/12\) while the bound keeps falling; switch to depth-2 trees and see the error reach 0 in round 3.
Pitfalls
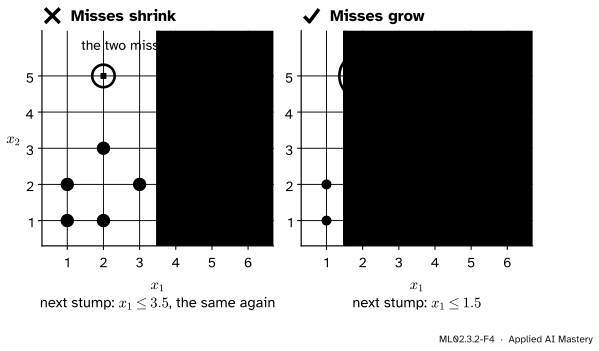
ML02.3.2-F4
Wrong beside right. With the sign of the exponent flipped, the misses shrink to \(1/26\) of the weight and the next round picks the same stump again. With the right sign they grow to one half and the next stump is new.
“Update with \(e^{\alpha_m y_i h_m(x_i)}\).”
The minus sign matters. Without it, the points the stump got right grow and its misses shrink, so the next round sees the same easy picture and fits the same stump again: the ensemble never moves. The update must make the stump’s own mistakes heavier.
“Once a stump has been used, it never comes back.”
The proof only says the newest stump has error \(\tfrac12\) right after its own update. Later rounds move the weights again, and an old stump can win once more. On the twelve points, \({x_1 \le 3.5}\) is chosen in round 1 and again in round 6.
“scikit-learn’s learner weights disagree with the formula.”
They are twice the \(\alpha_m\) of this lesson, because the library uses \({\ln\big((1-\epsilon)/\epsilon\big)}\). Every vote is doubled, so the sign of the sum, and every prediction, is unchanged.
Check yourself
Recall
1. Write the learner weight \(\alpha_m\) in terms of \(\epsilon_m\).
1.★ A stump has weighted error \({\epsilon = 1/4}\). Find \(\alpha\), \(e^{\alpha}\), \(Z\), and the multipliers that rescale its misses and its correct points.
Show solution
\({\alpha = \tfrac12 \ln 3 \approx 0.549}\) and \({e^{\alpha} = \sqrt3}\). Then \({Z = 2\sqrt{\tfrac14 \cdot \tfrac34} = \sqrt3/2 \approx 0.866}\). A miss is multiplied by \({1/(2 \cdot \tfrac14) = 2}\) and a correct point by \({1/(2 \cdot \tfrac34) = 2/3}\). Check: the misses held \(1/4\) and now hold \(1/2\); the rest held \(3/4\) and now hold \(1/2\).
2.★★ Continue the worked example by one update: the round-3 stump \({x_1 \le 5.5}\) has \({\epsilon_3 = 3/8}\). Find the weights of \((2,5)\), \((5,5)\) and \((1,1)\) after round 3.
Show solution
Misses are multiplied by \({1/(2 \cdot \tfrac38) = 4/3}\) and correct points by \({1/(2 \cdot \tfrac58) = 4/5}\). The point \((2,5)\) was missed: \({\tfrac{5}{24} \cdot \tfrac43 = \tfrac{5}{18}}\). The point \((5,5)\) was classified correctly (\({-1}\), left of 5.5): \({\tfrac{5}{16} \cdot \tfrac45 = \tfrac14}\). The point \((1,1)\) was correct: \({\tfrac{1}{24} \cdot \tfrac45 = \tfrac{1}{30}}\).
3.★★★ Show that \({Z_m \le 1}\), with equality only when \({\epsilon_m = \tfrac12}\). What does this say about the product \(Z_1 Z_2 \cdots Z_M\)?
Show solution
\({Z_m^2 = 4\epsilon(1-\epsilon)}\). Write \({\epsilon = \tfrac12 - \gamma}\). Then
with equality only when \({\gamma = 0}\). So each \({Z_m \le 1}\), and the product of the \(Z_m\) can only shrink as rounds are added, strictly whenever a learner beats a coin. Lesson ML02.3.3 shows that this product bounds the training error.
Summary card
AdaBoost reweights so that the newest learner’s misses hold exactly half the weight.
Sources. Each was opened and checked against this lesson on 15 November 2026.
Robert E. Schapire, The Boosting Approach to Machine Learning: An Overview, Springer, 2003. Figure 1 gives AdaBoost with the update that multiplies each weight by \(\exp(-\alpha_t y_i h_t(x_i))\) and divides by \(Z_t\), and equation (1) the choice \({\alpha_t = \tfrac12 \ln\big((1-\epsilon_t)/\epsilon_t\big)}\), as in the original paper of Freund and Schapire.
Robert E. Schapire, Explaining AdaBoost. Figure 1 states the same algorithm with labels in \({\{-1, +1\}}\) and the final hypothesis as the sign of \(\sum_t \alpha_t h_t(x)\).
Trevor Hastie, Robert Tibshirani and Jerome Friedman, The Elements of Statistical Learning, 2nd edition. Algorithm 10.1 (AdaBoost.M1) sets \({\alpha_m = \log\big((1-\text{err}_m)/\text{err}_m\big)}\) and multiplies the weights of the misses by \(\exp(\alpha_m)\).
scikit-learn 1.9, AdaBoostClassifier. Default weak learner a DecisionTreeClassifier with max_depth=1, n_estimators=50, learning_rate=1.0, early stop on a perfect fit, and the attributes estimator_weights_ and estimator_errors_.