Any independent set of vectors can be straightened into an orthonormal set that spans the same space. Learn the two moves of the Gram-Schmidt process, subtracting shadows and scaling to length one, work it by hand in two and three dimensions, and code it from scratch.
Carry out the Gram-Schmidt process by hand on two vectors in the plane and on three vectors in space.
Explain why subtracting the shadows of a vector on the earlier directions leaves something perpendicular to all of them.
State what the process returns, and what it does when the input vectors are dependent.
Implement Gram-Schmidt from scratch and check its output with a table of dot products.
In review. The maths and code on this page are checked by automated tests on every change, but an independent reader has not signed it off yet. Spot a mistake or a confusing step? Tell us.
The question
Real data never arrives with perpendicular axes. The columns of a data matrix lean on one another, the way height leans on weight. The last two lessons showed how easy everything becomes in an orthonormal basis. Can any set of independent vectors be straightened into one, without changing the space they span? And what is the recipe?
From the last lesson
1. Which single equation says that a square matrix \(\mat{Q}\) is orthogonal?
Show answer
\(\mat{Q}\T\mat{Q} = \mat{I}\). It says that the columns of \(\mat{Q}\) are orthonormal.
2. What is the inverse of an orthogonal matrix?
Show answer
Its transpose: \(\mat{Q}^{-1} = \mat{Q}\T\).
Intuition
Take two vectors \(\vect{a}_1\) and \(\vect{a}_2\) that are independent but not perpendicular. We want two orthonormal vectors \(\vect{q}_1, \vect{q}_2\) that span the same plane.
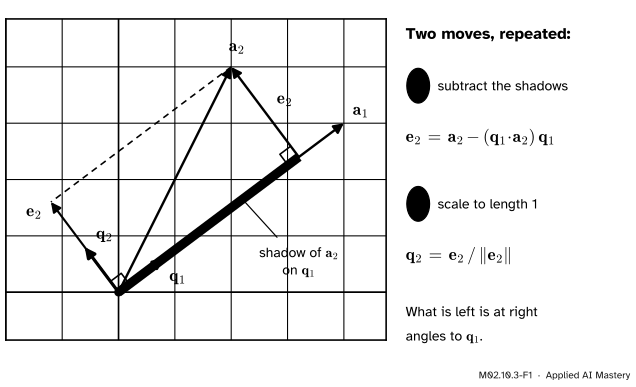
The first is easy: keep the direction of \(\vect{a}_1\) and scale it to length one. The trouble is \(\vect{a}_2\), because part of it points along \(\vect{q}_1\). That part is its shadow on \(\vect{q}_1\), the projection of lesson M02.3.4. Subtract the shadow, and what is left has no part along \(\vect{q}_1\) at all: it is perpendicular to it. Scale what is left to length one, and that is \(\vect{q}_2\).
M02.10.3-F1
Gram-Schmidt on two vectors. The shadow of \(\vect{a}_2\) on \(\vect{q}_1\) is subtracted, and what is left, \(\vect{e}_2\), is perpendicular to \(\vect{q}_1\). Scaling to length one gives \(\vect{q}_2\).
That is the whole of the Gram-Schmidt process: subtract the shadows, then scale to length one, for one vector after another. Each new vector loses its shadows on all the directions that are already finished.
Build it up
Work it through with numbers: \(\vect{a}_1 = (4, 3)\) and \(\vect{a}_2 = (2, 4)\).
M02.10.3-F2
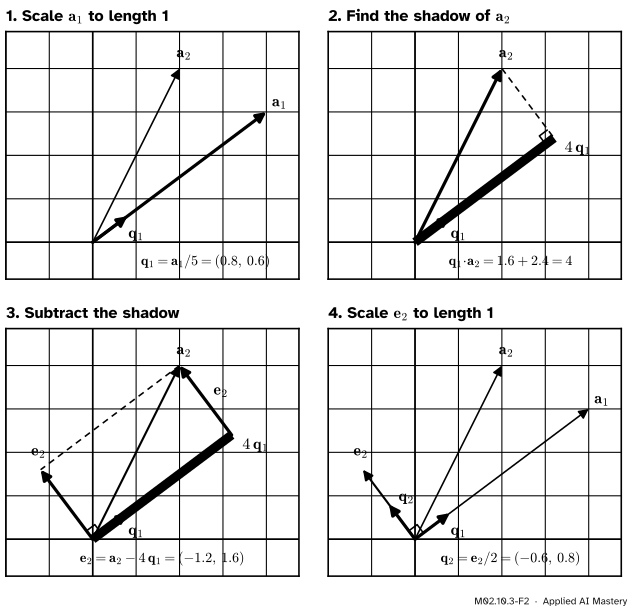
The four steps for two vectors of the plane. One move per frame.
Step 1. Scale \(\vect{a}_1\) to length one. Its length is \(\sqrt{4^2 + 3^2} = 5\), so \(\vect{q}_1 = \vect{a}_1 / 5 = (0.8, 0.6)\).
Step 2. Find the shadow of \(\vect{a}_2\). Because \(\vect{q}_1\) is a unit vector, the shadow of \(\vect{a}_2\) on it is \({(\vect{q}_1 \cdot \vect{a}_2)}\,\vect{q}_1\). The dot product is \({0.8 \cdot 2} + {0.6 \cdot 4} = 4\), so the shadow is \(4\,\vect{q}_1 = (3.2, 2.4)\).
Check the right angle: \({\vect{e}_2 \cdot \vect{q}_1} = -0.96 + 0.96 = 0\).
Step 4. Scale what is left. Its length is \(\sqrt{1.44 + 2.56} = 2\), so \(\vect{q}_2 = \vect{e}_2 / 2 = (-0.6, 0.8)\).
The result is the orthonormal basis of lesson M02.10.1, and the columns of the rotation matrix of lesson M02.10.2.
Step 5. A third vector loses two shadows. In space, a third vector \(\vect{a}_3\) may lean on both \(\vect{q}_1\) and \(\vect{q}_2\). Subtract its shadow on each:
For \(k = 1\) there is nothing to subtract, so \(\vect{e}_1 = \vect{a}_1\).
The colours match the figures: the given vectors, the sizes of the shadows, what is left and the finished directions. Three claims make the process work. Go through \(k = 1, 2, 3, \dots\) in order; each claim for one \(k\) may use the claims for smaller \(k\).
Claim 1: what is left is perpendicular to every earlier direction. Suppose \(\vect{q}_1, \dots, \vect{q}_{k-1}\) are already orthonormal, and take one of them, \(\vect{q}_i\). Dot it with the definition of \(\vect{e}_k\):
In the sum, \({\vect{q}_i \cdot \vect{q}_j}\) is zero except for \(j = i\), when it is one. So only one term survives, and it cancels the first. Scaling \(\vect{e}_k\) does not change its direction, so \(\vect{q}_k\) is perpendicular to the earlier \(\vect{q}\)’s as well, and it has length one. The list \(\vect{q}_1, \dots, \vect{q}_k\) is orthonormal.
Claim 2: the span never changes. For every \(k\), the vectors \(\vect{q}_1, \dots, \vect{q}_k\) span the same space as \(\vect{a}_1, \dots, \vect{a}_k\). Rearrange the two lines of the process:
So each \(\vect{a}_k\) is a combination of \(\vect{q}_1, \dots, \vect{q}_k\). In the other direction, \(\vect{q}_k\) is \(\vect{a}_k\) minus a combination of the earlier \(\vect{q}\)’s, divided by a number, and the earlier \(\vect{q}\)’s are combinations of \(\vect{a}_1, \dots, \vect{a}_{k-1}\) by this same claim for smaller \(k\). So each \(\vect{q}_k\) is a combination of \(\vect{a}_1, \dots, \vect{a}_k\). Whatever one family can reach, the other can.
Claim 3: the division is safe. Could \(\vect{e}_k\) be the zero vector? Then the first line of the process would say that \(\vect{a}_k\) equals the sum of its shadows. That sum is a combination of the earlier \(\vect{q}\)’s, and so, by Claim 2 for smaller \(k\), of \(\vect{a}_1, \dots, \vect{a}_{k-1}\). That contradicts independence (M02.2.3). So \(\norm{\vect{e}_k} > 0\) and the division can always be done.
Together: Gram-Schmidt turns any independent list into an orthonormal list with the same span. In particular every subspace of \(\R^m\) has an orthonormal basis.
Go deeper: on a computer, subtract from what is left so far
The process above takes every shadow from the original \(\vect{a}_k\). A second version takes each shadow from what is left so far: start with \(\vect{e} = \vect{a}_k\), and for \(j = 1, \dots, k - 1\) replace \(\vect{e}\) by \(\vect{e} - {(\vect{q}_j \cdot \vect{e})}\,\vect{q}_j\). In exact arithmetic the two agree. When shadow \(j\) is taken, \(\vect{e}\) differs from \(\vect{a}_k\) only by multiples of \(\vect{q}_1, \dots, \vect{q}_{j-1}\), which are perpendicular to \(\vect{q}_j\), so \({\vect{q}_j \cdot \vect{e}} = {\vect{q}_j \cdot \vect{a}_k}\).
With rounded numbers they differ. Rounding leaves each computed \(\vect{q}_j\) a hair away from perpendicular to the earlier ones. The first version takes every shadow from the whole of \(\vect{a}_k\), so those tiny errors arrive at the scale of \(\vect{a}_k\). When the vectors are nearly parallel, what is left is far shorter than \(\vect{a}_k\), and the errors are no longer small beside it. The second version measures each shadow on what is left so far, so it removes what is really there. The code section shows a case where the first version returns “perpendicular” vectors at \(60°\) to each other. Numerical libraries go further and avoid Gram-Schmidt altogether: LAPACK, which NumPy calls, builds the orthonormal vectors out of reflections.
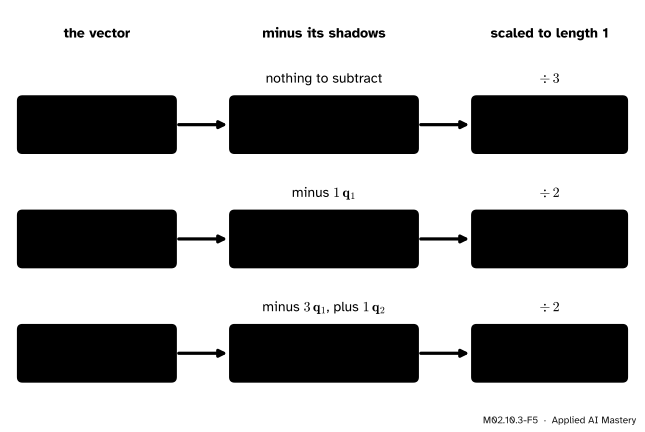
Its length is \(\tfrac13\sqrt{16 + 16 + 4} = 2\), so \(\vect{q}_3 = \tfrac13(2, -2, 1)\).
M02.10.3-F3
The third step, seen from a viewpoint where \(\vect{q}_1\) and \(\vect{q}_2\) span the floor. Subtracting the two shadows of \(\vect{a}_3\) removes everything that lies in the floor. What is left stands straight up.
Check. All three dot products between different \(\vect{q}\)’s are zero:
Each \(\vect{q}\) has squared length \(\tfrac19{(1 + 4 + 4)} = 1\). The three vectors are orthonormal.
Code
From scratch, with vectors as plain lists. The inner loop is the subtraction of shadows and the last lines are the scaling.
import mathdef dot(u, v):returnsum(a * b for a, b inzip(u, v))def gram_schmidt(vectors, tol=1e-12):"""Orthonormal vectors with the same span: subtract the shadows, then scale to length one.""" qs = []for a in vectors: e =list(a)for q in qs: shadow = dot(q, a) # how much of a lies along q e = [ei - shadow * qi for ei, qi inzip(e, q)] length = math.sqrt(dot(e, e))if length < tol:raiseValueError("dependent vectors: nothing is left of this one") qs.append([ei / length for ei in e])return qsfor q in gram_schmidt([(4, 3), (2, 4)]):print([round(x, 10) for x in q])print("three times the vectors of the worked example:")for q in gram_schmidt([(1, 2, 2), (-1, 0, 2), (3, 1, 2)]):print([round(3* x, 10) for x in q])
[0.8, 0.6]
[-0.6, 0.8]
three times the vectors of the worked example:
[1.0, 2.0, 2.0]
[-2.0, -1.0, 2.0]
[2.0, -2.0, 1.0]
A dependent list is caught at the vector that adds nothing new:
try: gram_schmidt([(1, 2, 2), (-1, 0, 2), (0, 2, 4)]) # the third is the sum of the first twoexceptValueErroras error:print("stopped:", error)
stopped: dependent vectors: nothing is left of this one
With NumPy the vectors become the columns of a matrix, and all the shadows of one column come off in a single line. The flag chooses between the two versions of the “deeper” note above.
import numpy as npdef gram_schmidt_columns(A, from_what_is_left=False):"""Gram-Schmidt on the columns of A. Returns a matrix with orthonormal columns.""" A = np.asarray(A, dtype=float) Q = np.zeros_like(A)for k inrange(A.shape[1]): e = A[:, k].copy()for j inrange(k): source = e if from_what_is_left else A[:, k] e = e - (Q[:, j] @ source) * Q[:, j] Q[:, k] = e / np.linalg.norm(e)return QA = np.array([[1.0, -1.0, 3.0], [2.0, 0.0, 1.0], [2.0, 2.0, 2.0]]) # columns: the three vectors of the worked exampleQ = gram_schmidt_columns(A)print(np.round(3* Q, 10) +0.0)print("orthonormal columns:", np.allclose(Q.T @ Q, np.eye(3)))
Now a hard case for rounding: three columns that are almost parallel.
tiny =1e-8B = np.array([[1.0, 1.0, 1.0], [tiny, 0.0, 0.0], [0.0, tiny, 0.0], [0.0, 0.0, tiny]])def worst(Q):"""The largest error in the table of dot products."""returnfloat(np.abs(Q.T @ Q - np.eye(Q.shape[1])).max())textbook = worst(gram_schmidt_columns(B))careful = worst(gram_schmidt_columns(B, from_what_is_left=True))library = worst(np.linalg.qr(B)[0])print(f"shadows taken from the original vector: {textbook:.1e}")print(f"shadows taken from what is left so far: {careful:.1e}")print(f"NumPy, which uses reflections: {library:.1e}")
shadows taken from the original vector: 5.0e-01
shadows taken from what is left so far: 7.1e-09
NumPy, which uses reflections:          6.7e-16
The textbook version reports an error of 0.5: its second and third vectors have a dot product of one half, so they stand at \(60°\), not \(90°\). Taking shadows from what is left so far keeps the error near \(10^{-8}\), and the library routine is accurate to rounding. Use the formula to understand, and the library to compute.
Explore
M02.10-X1
Gram-Schmidt stepper
Press Step to run Gram-Schmidt one move at a time. Drag the round handles, or use the sliders, to change the vectors at any stage and watch every later vector follow. Switch to three vectors to see the third one lose its shadow on the plane of the first two.
Things to try:
Step through the starting vectors \((4, 3)\) and \((2, 4)\). Do the numbers in the read-out match the four steps above?
At the last step, drag \(\vect{a}_2\) around. The pair \(\vect{q}_1, \vect{q}_2\) stays at a right angle whatever you do. When does \(\vect{q}_2\) jump to the other side of \(\vect{q}_1\)?
Drag \(\vect{a}_2\) onto the line of \(\vect{a}_1\). What is left after the subtraction, and what does the read-out say about \(\vect{q}_2\)?
Make \(\vect{a}_2\) already perpendicular to \(\vect{a}_1\), for example \((-3, 4)\). How long is the shadow now?
Switch to three vectors in space and step to the end. Choose \(\vect{a}_3\) under Move a vector and set it to \((2, 2, 0)\), which is \(\vect{a}_1 - \vect{a}_2\) and so lies in the plane of the first two. What is left of it now?
Pitfalls
M02.10.3-F4
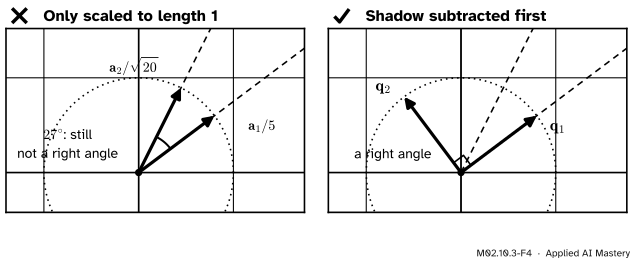
Wrong beside right. Scaling vectors to length one does not change the angle between them. Only subtracting the shadow makes the second vector perpendicular to the first.
“Scale every vector to length one and the set is orthonormal.”
Scaling fixes lengths, not angles. \((4, 3)/5\) and \((2, 4)/\sqrt{20}\) both have length one, but they are still about \(27°\) apart, as \(\vect{a}_1\) and \(\vect{a}_2\) were. In data work this is the difference between standardising features, which rescales each one, and decorrelating them, which needs a subtraction like the one here.
“For the third vector, subtract its shadow on the second.”
It must lose its shadow on every earlier direction. In the worked example, subtracting only the shadow on \(\vect{q}_2\) leaves \(\vect{a}_3 + \vect{q}_2 = \tfrac13(7, 2, 8)\), whose dot product with \(\vect{q}_1\) is \(\tfrac19{(7 + 4 + 16)} = 3\), not zero.
“Gram-Schmidt works on any list of vectors.”
It needs independent vectors. If \(\vect{a}_k\) is a combination of the earlier ones, its shadows add up to the whole of it, \(\vect{e}_k\) is the zero vector, and there is nothing to scale. That zero is useful: it is how the process reports a dependent vector. On a computer the leftover is rarely exactly zero, so code compares its length with a small tolerance.
Check yourself
Recall
1. What are the two moves of the Gram-Schmidt process?
Show answer
Subtract from the new vector its shadows on all the directions already found, then scale what is left to length one.
2. What is the shadow of a vector \(\vect{a}\) on a unit vector \(\vect{q}\)?
Show answer
\({(\vect{q} \cdot \vect{a})}\,\vect{q}\): the dot product says how much of \(\vect{a}\) lies along \(\vect{q}\).
3. After the shadows are subtracted, what is true of what is left, \(\vect{e}_k\)?
Show answer
It is perpendicular to every earlier \(\vect{q}_i\), because \({\vect{q}_i \cdot \vect{e}_k} = {\vect{q}_i \cdot \vect{a}_k} - {\vect{q}_i \cdot \vect{a}_k} = 0\).
4. What does the output \(\vect{q}_1, \dots, \vect{q}_n\) have in common with the input \(\vect{a}_1, \dots, \vect{a}_n\)?
Show answer
The span. For every \(k\), the first \(k\) of the \(\vect{q}\)’s span the same space as the first \(k\) of the \(\vect{a}\)’s.
5. What happens when one of the input vectors is a combination of the earlier ones?
Show answer
Nothing is left after the subtraction: \(\vect{e}_k = \vect{0}\), and it cannot be scaled to length one. The process has detected that the vectors are dependent.
Exercises
1.★ Apply Gram-Schmidt to \(\vect{a}_1 = (3, 4)\) and \(\vect{a}_2 = (1, 3)\).
Show solution
\(\norm{\vect{a}_1} = 5\), so \(\vect{q}_1 = (0.6, 0.8)\). The shadow has size \({\vect{q}_1 \cdot \vect{a}_2} = 0.6 + 2.4 = 3\), so the shadow is \(3\,\vect{q}_1 = (1.8, 2.4)\). What is left is \(\vect{e}_2 = {(1 - 1.8,\; 3 - 2.4)}\), which is \((-0.8, 0.6)\). Its length is \(\sqrt{0.64 + 0.36} = 1\), so \(\vect{q}_2 = (-0.8, 0.6)\). Check: \({\vect{q}_1 \cdot \vect{q}_2} = -0.48 + 0.48 = 0\).
2.★★ Apply Gram-Schmidt to \(\vect{a}_1 = (1, 1, 0)\), \(\vect{a}_2 = (1, 0, 1)\) and \(\vect{a}_3 = (0, 1, 1)\).
Show solution
\(\vect{q}_1 = \tfrac{1}{\sqrt{2}}(1, 1, 0)\).
\({\vect{q}_1 \cdot \vect{a}_2} = \tfrac{1}{\sqrt{2}}\), and \(\tfrac{1}{\sqrt{2}}\,\vect{q}_1 = \tfrac12(1, 1, 0)\), so
Its length is \(\tfrac23\sqrt{3}\), so \(\vect{q}_3 = \tfrac{1}{\sqrt{3}}(-1, 1, 1)\). The three dot products \(\tfrac{1}{\sqrt{12}}{(1 - 1 + 0)}\), \(\tfrac{1}{\sqrt{6}}{(-1 + 1 + 0)}\) and \(\tfrac{1}{\sqrt{18}}{(-1 - 1 + 2)}\) are all zero.
3.★★★ Let \(\vect{a}_1, \dots, \vect{a}_{k-1}\) be independent, and let \(\vect{a}_k\) be a combination of them. Prove that Gram-Schmidt gives \(\vect{e}_k = \vect{0}\). Then confirm it for \(\vect{a}_1 = (1, 2, 2)\), \(\vect{a}_2 = (-1, 0, 2)\) and \(\vect{a}_3 = \vect{a}_1 + \vect{a}_2\).
Show solution
By Claim 2, \(\vect{a}_k\) lies in the span of \(\vect{q}_1, \dots, \vect{q}_{k-1}\), so \(\vect{a}_k = c_1\vect{q}_1 + \cdots + c_{k-1}\vect{q}_{k-1}\) for some numbers \(c_j\). Dot both sides with \(\vect{q}_i\). The \(\vect{q}\)’s are orthonormal, so every term on the right vanishes except \(c_i\), and \(c_i = {\vect{q}_i \cdot \vect{a}_k}\). Therefore \(\vect{a}_k = \sum_j {(\vect{q}_j \cdot \vect{a}_k)}\,\vect{q}_j\), which is exactly what the process subtracts from \(\vect{a}_k\). So \(\vect{e}_k = \vect{0}\).
For the numbers, \(\vect{a}_3 = (0, 2, 4)\), with \(\vect{q}_1 = \tfrac13(1, 2, 2)\) and \(\vect{q}_2 = \tfrac13(-2, -1, 2)\) from the worked example. The shadows have sizes \({\vect{q}_1 \cdot \vect{a}_3} = \tfrac13{(0 + 4 + 8)} = 4\) and \({\vect{q}_2 \cdot \vect{a}_3} = \tfrac13{(0 - 2 + 8)} = 2\). Then
Result. Orthonormal \(\vect{q}\)’s, with the same span as the \(\vect{a}\)’s at every stage.
Dependent input. Then some \(\vect{e}_k = \vect{0}\): nothing new was added.
Sources and next steps
Sources. Each was opened and checked against this lesson on 12 November 2026.
Sheldon Axler, Linear Algebra Done Right, 4th edition (open access), Section 6B. Result 6.32, the Gram-Schmidt procedure, states the subtraction and the scaling, and proves that the span is the same at every stage. A margin note on the page before credits Jørgen Gram and Erhard Schmidt with popularising the algorithm.
Marc Deisenroth, Aldo Faisal and Cheng Soon Ong, Mathematics for Machine Learning, Section 3.8.3. Equations (3.67) and (3.68) define Gram-Schmidt as subtracting from each vector its projection on the span of the earlier ones.
Gilbert Strang, Orthogonal matrices and Gram-Schmidt, MIT OpenCourseWare 18.06SC, lecture 17. Its overview: “a procedure for converting any basis to an orthonormal one”.
David Austin, Understanding Linear Algebra, Section 6.4. Subsection 6.4.2 gives the same algorithm with the division by \({\vect{w}_i \cdot \vect{w}_i}\) written out, for vectors that are not yet scaled.